AAMAS 2024 · Oral
Proceedings ↗ · arXiv ↗ · Code ↗
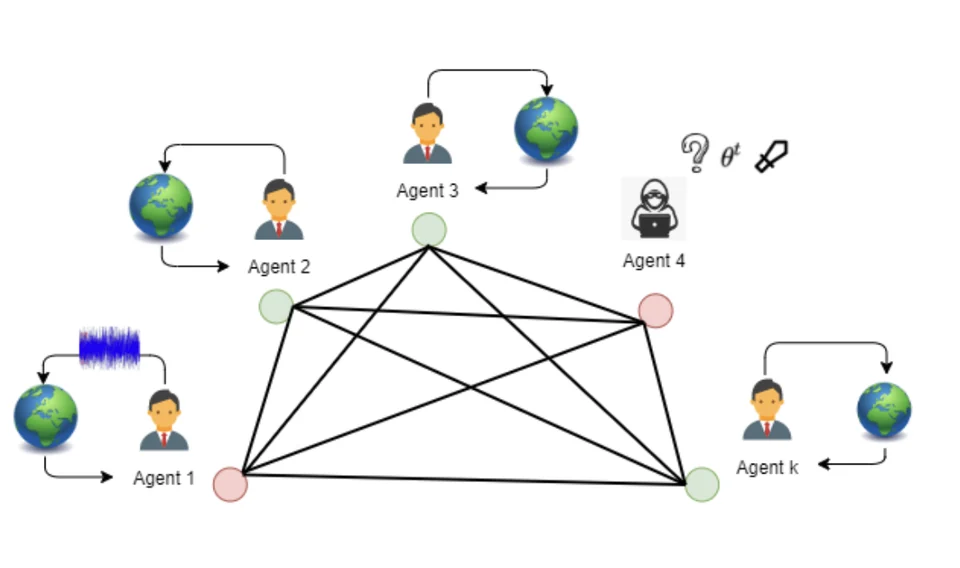
Agents collaborate on reinforcement learning while acting in local environments and without exchanging raw trajectories. This work combines robust aggregation with Byzantine-resilient agreement to remove dependence on a trusted central aggregator. The policy-gradient methods provide convergence guarantees and are evaluated under honest participation and several Byzantine attacks.